Microsoft Works to Restore Services After Server Failure Hits Outlook and Teams Globally
A sudden failure that took critical servers offline disrupted access to Microsoft 365, Outlook, and Teams globally, leaving engineers scrambling to rebalance traffic loads and restore enterprise communications.
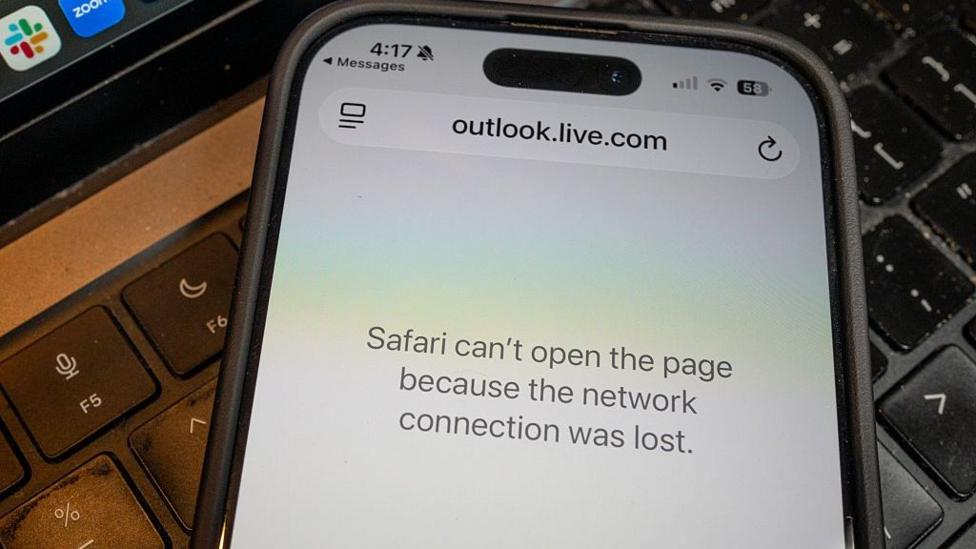
Microsoft worked urgently to restore critical cloud services following an extensive infrastructure outage that cut off access to Outlook, Teams, and Microsoft 365 for tens of thousands of users worldwide. The incident disrupted everyday communication across businesses, educational institutions, and government offices that depend heavily on the software giant's enterprise suite. Incident monitoring sites registered sharp spikes in complaints as workers found themselves locked out of vital workplace tools at the start of the business day.
In official status updates detailing the disruption, the company explained that the failure originated when a critical volume of servers unexpectedly became unavailable. The sudden reduction in active server capacity triggered severe operational strain across Microsoft's surviving infrastructure as systems scrambled to absorb diverted user traffic. Technical specialists immediately mobilized to determine why key hardware nodes dropped from the network cluster.
Microsoft clarified that the disruption was not caused by a malicious cyberattack or an unprecedented spike in global internet activity. Instead, technical diagnostics indicated that the issue emerged during automated system health evaluations that misclassified healthy machines. That automated sequence mistakenly took operational servers out of service, cascading into widespread access failures across connected platforms.
The technical breakdown rippled across multiple core components of the broader Microsoft 365 product ecosystem. In addition to users experiencing persistent connection errors in Outlook and frozen chats in Teams, disruptions spread to SharePoint, OneDrive, and the AI-driven assistant Copilot. Several connected enterprise applications and cloud-dependent workflows also reported severe latency or complete downtime.
The timing of the outage amplified its impact on corporate productivity across multiple continents and time zones. With critical lines of digital communication abruptly severed, organizations were forced to postpone virtual conferences, delay project deadlines, and reroute urgent correspondence through backup systems. Information technology administrators around the world scrambled to confirm whether the disruption was localized or part of a wider service breakdown.
In response to the mounting disruption, Microsoft network engineers initiated manual rerouting procedures to direct traffic toward unaffected data centers. Engineering crews deployed targeted software adjustments and rolled out revised operational checks designed to bring isolated servers back into the active pool. The company stressed that balancing traffic loads remained its top priority while stabilizing affected network nodes.
Recovery across affected markets progressed gradually, resulting in an uneven restoration timeline for different organizations and geographies. Many enterprise users noted fluctuating performance throughout the recovery phase, with email access returning intermittently before encountering synchronization errors or renewed connection drops. System administrators continued to report varying degrees of functionality well into the restoration process.
The widespread disruption once again highlighted the deep operational vulnerability inherent in modern corporate reliance on centralized cloud ecosystems. Because a dominant share of international business communications is anchored to a small handful of hyperscale providers, minor internal engineering flaws can instantly cascade into broad economic and institutional gridlock. Analysts noted that recurring cloud outages inevitably reignite discussions around digital resilience and multi-vendor redundancy.
Microsoft maintained that its technical teams would continue monitoring telemetry and system performance metrics until full service reliability was verified globally. The company indicated that a detailed post-incident report would follow once all platforms stabilized completely, outlining root causes and procedural safeguards to prevent similar occurrences. In the interim, subscribers were advised to follow administrative service dashboards for the latest region-specific operational updates.
Primary source: BBC Technology. Newzly rewrites and structures source reporting for clarity; verify critical details at the original.